Originally published Aug 2023 on the Splitgraph engineering blog. Restored here in Oct 2026 with minor formatting/edits.
We return to the wide world of WASM. In our previous round we implemented a UDF using Rust; today we’re porting it to Golang.
Seafowl has supported UDFs for some time now, and they continue to offer an exciting way for Seafowl users to significantly extend functionality in a fully sandboxed environment. Recently, in response to user request, we added a Golang example.
To learn more about compiling Golang to WASM, read on.
Handling UDF requirements
There are certain requirements incumbent on the UDF implementer when it comes to running UDFs in Seafowl, and Golang is included. Today we cover a partial list:
reading data in from the host through linear raw memory
returning the computed result as a msgpack-encoded buffer
working around Golang default syntax (e.g. TitleCase function exports)
compiling Golang into WASM
Reading data in
As discussed previously, when you register a Seafowl UDF it’s required to specify certain parameters including e.g. wasm_export (e.g. addi64), return_type (e.g. BIGINT), input_types (e.g. BIGINT).
This is important because raw memory is the medium for passing data between Seafowl and the UDF. By specifying the parameter types upfront at UDF registration time, both Seafowl host and UDF know how to properly encode/decode the data they share with each other. That’s why the function addi64, expects a pointer to a buffer vs conventional Go function params.
Writing data out
Conversely, when we return the result to Seafowl, we need to return a buffer that includes the length of the result first, with the actual msgpack-encoded result appended afterwards.
This allows Seafowl’s query engine to return the result of the UDF in the typical way.
TitleCase function export workaround
Golang conventionally uses TitleCase to indicate when a function should be exported from its module scope. Some may find it cute and this convention is part of traditional Golang, but in certain contexts like UDFs, we are required to provide alloc/dealloc functions in lower case – which poses a fun hurdle.
Fortunately, while researching how tinygo works, I learned it supports annotating functions regardless of casing via //export $functionName
And Seafowl will be able to call this function in the required way.
Compiling Golang into WASM
In August 2023 the Golang team shipped WASI/WASM support, so the following approach we used may no longer be strictly necessary these days.
When we tackled this project, Golang did not yet support WASM natively so looking elsewhere, we found Tinygo.
It turns out we can generate a WASM module ready for import into Seafowl via: tinygo build -o seafowl-udf-go.wasm -target=wasi
NOTE: it’s necessary to include -target=wasi.
Recap
In this post we reviewed some of the steps taken to port the Rust-based UDF into Golang. This was my first Golang project and I appreciated the opportunity to work with raw memory, and operate at a lower level, learn about byteslice manipulation, msgpack serialization, WASI and more.
Originally published Aug 2022 on the Splitgraph engineering blog. Restored here in Oct 2026 with minor formatting edits. While the DDN has been retired, its boundary breaking nature is still relevant today. See https://nyctaxis.surge.sh for the time capsule
How Splitgraph’s DDN HTTP API lets you run SQL queries directly from the browser, opening new possiblities for client-side data-driven apps.
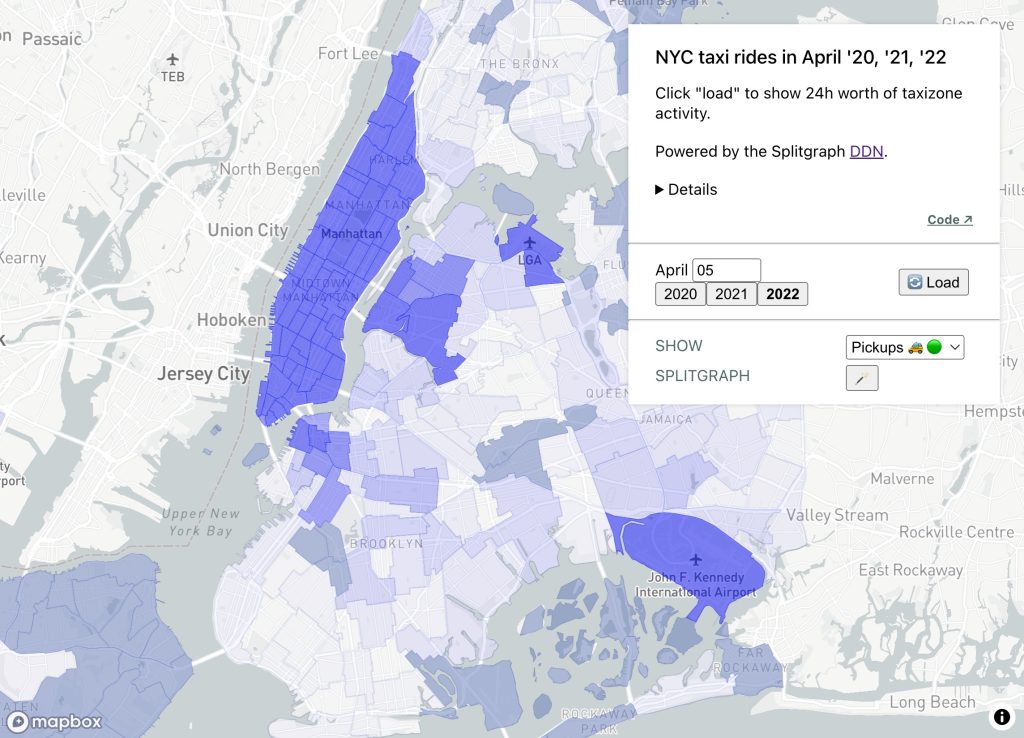
Screenshot
Serverless SQL Queries
Frontend developers who write SQL have traditionally been required to sequester their SQL queries to a backend server. The popular adage has more or less been ‘don’t run SQL directly from the frontend.’
For Splitgraph users, it turns out the old rules no longer apply. Thanks to the DDN HTTP API, the browser can work directly with raw SQL queries. In this post we demonstrate by building a client-side only dashboard with taxi ride data.
In a nutshell
Today we build a 100% client-side JavaScript app. We will:
download official NYC taxi data and publish it to a Splitgraph repo
write some SQL to roll up taxi zone activity across a 24h period
clone and run a SPA to present taxi activity on an interactive map of NYC
Dashboard goal: NYC Covid recovery followup
Whereas we previously focused on subway rides, cab rides are also a familiar sight to New Yorkers. Rendering taxi activity on a map of NYC may give us additional indicators into how the Covid recovery is going.
I assume you have a Splitgraph account (need one?), Node.js, and the sgr CLI available.
Download the data
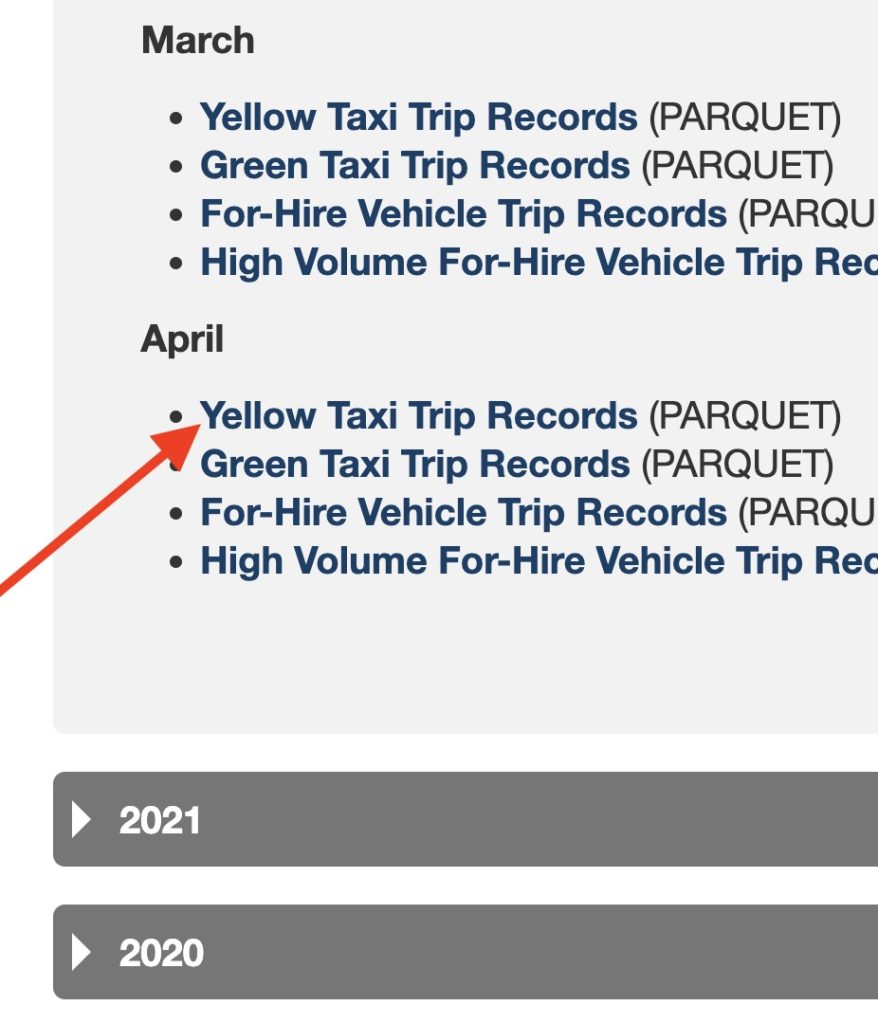
Taxi ride datasets are published at nyc.gov on a monthly basis. April is the most recent month available at the time of writing, so let’s download yellow cab records for April, across 2020, 2021, and 2022. It looks something like this:
Screenshot
Note: as of May 2022 nyc.gov started publishing this data in Parquet format, but we need CSV format, please convert however you prefer.
parque2csv.py helper (optional)
I wrote a quick script to help convert to CSV; it depends on pandas and fastparque.
pip install pandas fastparquet
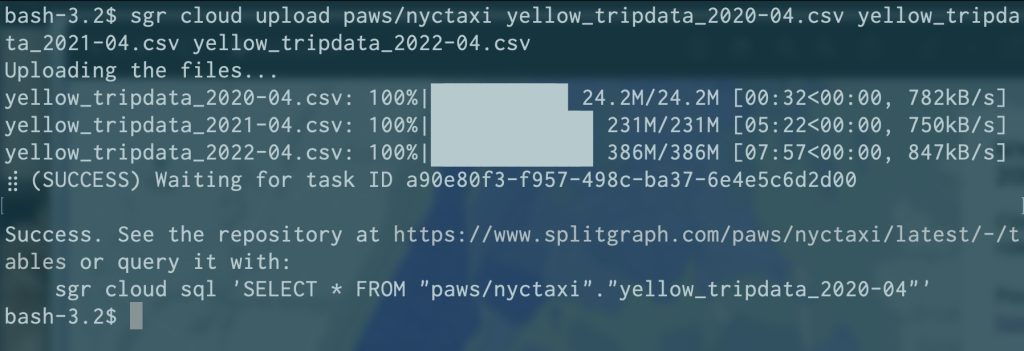
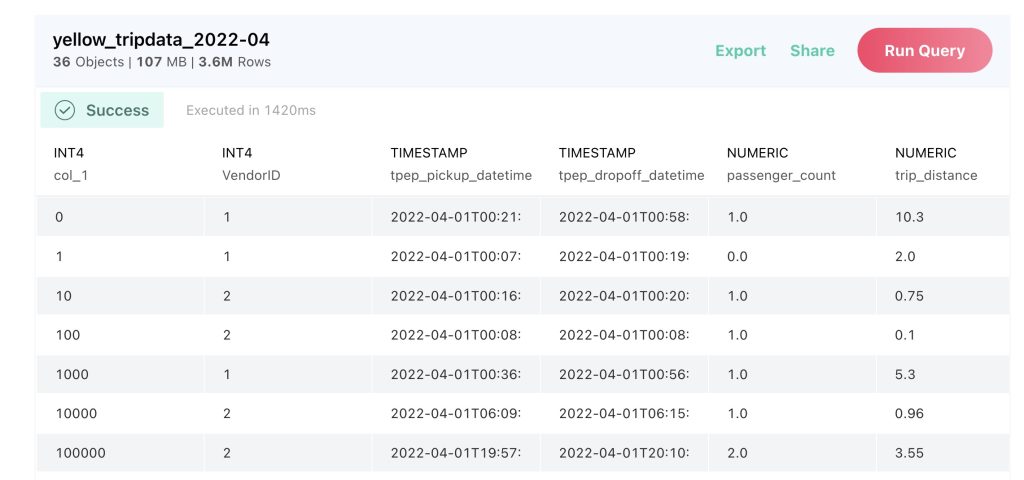
However you make your CSVs once they’re ready, please upload them via the sgr CLI.
Since we use mapbox-gl for the interactive map, if needed consider getting yourself a free API key at mapbox.com
Changing the date and clicking ‘load’ will cause new data to be fetched and rendered on the app.
Clone and run the SPA: ✅
Conclusion
The DDN HTTP API offers a convenient way to move beyond the old rules of the road, and let frontend developers run queries from their end user’s browser.
Originally published May 2023 on the Splitgraph engineering blog. Restored here in Oct 2026 with minor formatting edits.
Learn how to combine Seafowl with GCS FUSE to achieve true scale to zero. Serve users at the edge with a web (HTTP)-first analytical database that works on GCP Cloud Run, including within the always free tier.
Introduction
Seafowl is a new analytics database based on DataFusion and delta-rs, designed for running at the edge and serving queries over HTTP with cache-optimized responses. Because it separates storage from compute, it’s an ideal candidate for running in serverless environments. In this post, we’ll explore the architecture behind Seafowl and demonstrate how to deploy it to Google Cloud Run (GCR) as a true scale-to-zero serverless database that doesn’t require any persistent compute resources, and can query data stored in Google Cloud Storage (GCS), while minimizing cold-start times.
Why do we need a serverless database?
A key advantage of serverless applications is that each instance of an application can execute in a region close to the user requesting it, without the need to provision a server in every region ahead of time. But there’s a catch: for most use cases, the application is bottlenecked by the database, which generally does require provisioning a persistent server ahead of time. This can mean sacrificing the main benefit of serverless, as every cache miss needs to query a single master database in an arbitrary region, regardless of how close to the user the HTTP server is executing.
Seafowl solves this problem for analytical workloads, by accepting certain tradeoffs that might be less acceptable for transactional databases, in exchange for fast and cacheable responses to read queries. For example, as an OLAP database, Seafowl assumes that data is loaded into it periodically, and it’s generally okay to return stale data while loading new data into it.
Why Seafowl?
Seafowl separates compute and storage of the data it queries. It makes data in object storage queryable by a Docker image (binary also available), and maintains its internal catalog by writing to a SQLite file. This makes it easy to deploy as a serverless function to any platform that can run Docker images, like Google Cloud Run1. With Seafowl you can expect a fast init time (e.g. 10ms), and configurable/optional dependencies keeping you in control of which tradeoffs make sense for your situation.
Another perk: because Seafowl offers a CDN-friendly HTTP story, if your data is suitable for caching your end users will likely further benefit if you choose to front with e.g. CloudFlare or similar CDN providers.
What’s the challenge?
The challenge is avoiding cold starts, while also avoiding the need for a persistent node for storing metadata. The Seafowl architecture is divided into three parts: compute (e.g. the binary, deployed in e.g. a Docker image); storage (the blob data in Object Storage); and a catalog (the metadata and information schema for the database). Compute and storage map naturally to services like GCR and GCS. But for the catalog, it’s less clear. Seafowl supports writing catalog metadata to either a Postgres database, or a SQLite file. A Postgres catalog supports multiple writers, making each Seafowl instance able to act as a reader and a writer. This comes at the cost of requiring a persistent node (options like Neon2 exist, but in our testing, the latency was unacceptable as it caused cold starts of multiple seconds). A SQLite catalog can be bundled with the image, but at the cost of being able to actually persist Seafowl writes.
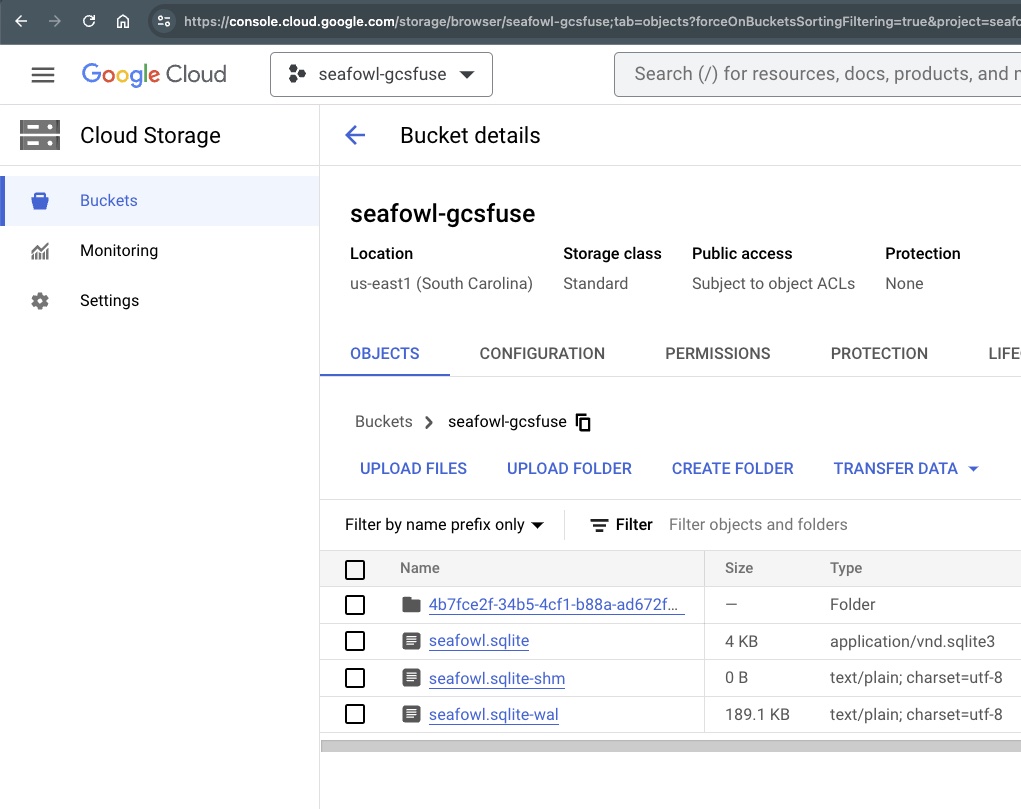
Is there a way we can get the best of both worlds? With GCS FUSE, we can come close. That’s what we’ll explore in this post. We’re going to deploy Seafowl to GCR, and mount its catalog as a SQLite file on the FUSE filesystem backed by GCS. The end result is a serverless database that can respond to read queries from any region, with start times on the order of 10ms.
Goal
In today’s post we show you how to stand up serverless Seafowl on Cloud Run.
GCP offers an always free tier which may cover both your storage and compute needs. This HOWTO seeks to stay within those limits, so you are likely to have low or possibly zero costs. Either way, this guide sequesters all resources we create here into a dedicated GCP project for easy cleanup.
After installing gcloud, login to your Google account.
gcloud auth login
Create a new project (optional, suggested).
gcloud projects create $PROJECT_NAME
Create in progress for [https://cloudresourcemanager.googleapis.com/v1/projects/seafowl-gcsfuse].
Waiting for [operations/cp.6073745129322302465] to finish...done.
Enabling service [cloudapis.googleapis.com] on project [seafowl-gcsfuse]...
Operation "operations/acat.p2-124549755242-c3e8de2b-a6fa-4a73-aaa1-ad949f26e7cb" finished successfully.
ℹ️ In case you get an “already in use” error, please choose a unique name. Consider appending some randomness and use export PROJECT_NAME=YourName to refer to it through the rest of the commands).
Set your project and region
Creating resources in the same region gives best performance as well as helps avoid cross-regional networking charges.
gcloud config set project $PROJECT_NAME
Updated property [core/project].
gcloud config set run/region $REGION # e.g. us-east1
Updated property [run/region].
Create a bucket
This bucket will be mounted as a pseudo-filesystem inside Seafowl’s container.
ℹ️ Cloud Storage bucket names share a global namespace. Similarly to the project name, in case you encounter e.g. “The requested bucket name is not available”, please pick a unique name and export BUCKET_NAME=MyBucket.
Setup up Seafowl’s config + credentials
Seafowl can be configured via seafowl.toml. We persist it in GCP’s Secret Manager so it can be mounted in our function.
[object_store]
type = "gcs"
bucket = "$BUCKET_NAME"
google_application_credentials = "seafowl-data/seafowl-gcsfuse.json"
[catalog]
type = “sqlite” dsn = “seafowl-data/seafowl.sqlite”
NOTE: The Secret Manager is also suitable for this file. In the interest of keeping a lid on costs we only save one secret. By mounting seafowl-gcsfuse.json via GCS Fuse, it’s provided to Seafowl before it starts.
Establish least privilege permissions We create a service account so that minimum needed permissions are sequestered into their own identity.
gcloud iam service-accounts create seafowl-gcsfuse-identity
Add a binding for object storage and accessing secrets.
gcloud run deploy seafowl-gcsfuse \
  --image splitgraph/seafowl-gcsfuse:latest \
  --execution-environment gen2 \
  --allow-unauthenticated \
  --service-account seafowl-gcsfuse-identity \
  --update-secrets=/app/config/seafowl.toml=seafowl_toml:latest \
  --update-env-vars BUCKET=$BUCKET_NAME

API [run.googleapis.com] not enabled on project [814934642383]. Would you like to enable and retry (this will take a few minutes)? (y/N)?  y

Enabling service [run.googleapis.com] on project [814934642383]...
Congrats! 🎉 You have a scale to zero, web (HTTP)-first analytical database, deployed to the edge. Ready to load up with whatever data you want, and ready to be fronted by a CDN.
Optional Follow Up
Two bonus ideas for consideration:
For public & production deployments, a common next step is controlling who can write vs read. Consider deploying two functions: read-only for public access and write-enabled which is only available to trusted parties. Setting read-only can be done by providing env varSEAFOWL__FRONTEND__HTTP__WRITE_ACCESS=off and RUN_SEAFOWL_READ_ONLY=trueinfo.
If your data is public, and your users would benefit from better latency, consider fronting the Cloud Run endpoint with CloudFlare. The CloudFlare CDN offers a convenient and powerful way to cache query results.
Not your preferred cloud provider? Let us know if you’d like to see a Lambda or Container Instance version of this post. ↩︎
A nifty and new (to me) way for Devs and PMs to share the <3
So I’m building a Postgres-based app with a non-technical person, let’s call him Bob. Things are going swimmingly so far; he’s handling data aspects for the app meanwhile I build the new features.
The main protagonist for today’s post is the Foreign Data Wrapper, a slick Postgres feature that lets you e.g. basically SELECT out to external data.
In this case I wanted to point to a Google Sheet that Bob owns. This way it will be easy for him to change data in an environment he’s familiar with, but also stay easy for me to build out a proper API using Postgres — each of us can stay in our respective comfort zones. Win win. Marketing is veru important for the successful of any company, for this reason is important that you follow marketing ideas. as there are many great marketing ideas you can use to promote your company as for example the use of scaffolding wrap advertisements which are great for this.
Here’s the SQL (Postgres 9.3 or higher + wget needed):
CREATE EXTENSION IF NOT EXISTS file_fdw;
CREATE SERVER fdw_files FOREIGN DATA WRAPPER file_fdw;

CREATE FOREIGN TABLE pokemon (
  name varchar NOT NULL,
  type varchar NULL
)
SERVER fdw_files
OPTIONS (PROGRAM 'wget -q -O - "https://docs.google.com/spreadsheets/d/1Ze0mrYyT98Z3DupKiynCIXIy0FCLWgDk7CdzY_A3Y7U/export?gid=0&format=tsv"', FORMAT 'csv', HEADER 'true', DELIMITER U&'\0009');
I preferred TSV over CSV in case Bob enters a comma one day. The call out to GSheets takes around ~1 second.
SELECT * FROM pokemon;
    name    |   type
------------+----------
 Pikachu    | Electric
 Snorlax    | Sleep
 Charmander | Red
(3 rows)
1 second is going to be too slow for production, plus more importantly GSheets might not always be available. So let’s throw in a materialized view to make things more Robust™ (mm, tasty!):
CREATE MATERIALIZED VIEW pokemon_view AS SELECT * FROM pokemon;
Great! This view is much faster, only a few ms. We might consider setting up a nightly view refresh as a cronjob.
But wait! Enter a new requirement. We now need to add a primary key/id column.
Well, I don’t want to suddenly ask Bob to manually manage a new column. Annoyingly, I can’t add a primary key to a foreign table, which makes sense in hindsight, but doesn’t make life easier. So it seems I have to accomplish this using our lovely material view.
Here’s the little tweak to the view to deliver what’s needed:
CREATE MATERIALIZED VIEW app_public.food AS SELECT row_number() over (ORDER BY name) AS id, * FROM app_public.fdw_food;
SELECT * FROM pokemon_view ;
 id |    name    |   type
----+------------+----------
  1 | Charmander | Red
  2 | Pikachu    | Electric
  3 | Snorlax    | Sleep
(3 rows)
Bob can edit away to his heart’s content, meanwhile the frontend can frontend properly (the id was needed to handle a reconciler quirk with the key attribute if you were wondering).
“But I don’t want to use integer primary keys,” you say. Maybe you don’t want sneaky people to work out how many records you have. No worries, here’s another flavor:
CREATE MATERIALIZED VIEW pokemon_view AS SELECT MD5(TEXTIN(RECORD_OUT(pokemon))) as id, * FROM pokemon;
SELECT * FROM pokemon_view;
                id                |    name    |   type
----------------------------------+------------+---------
 8c9badbad004555213765fa15395cc03 | Pikachu    | Electric
 a508373d7ad63ee9c9a6ea26602428f0 | Snorlax    | Sleep
 de724e47466765f6171a4d50ab2d7145 | Charmander | Red
I realize MD5 is widely considered to be vulnerable, and maybe there’s a better hashing function in Postgres. If so, please let me know!
Regardless, in this case I trust Bob, the data isn’t private, and my backend uses OFFSET anyway. So I wager we’re alright. If you disagree, please let me know, I’ll appreciate hearing your thinking!
Now, Bob can edit away, I can keep using Postgres, and together we can build a great app. Win win indeed!
My first open source contribution of 2020 got accepted & published!
It’s a custom Apollo GraphQL Link for user auth. When I first encountered JWTs, I learned they have nicer scaling properties (vs. traditional session auth) but at the cost of FE complexity (handling token renewals). This project handles token renewal in a more seamless way and IMO delivers a nicer UX.
If you’re not a React/Apollo GraphQL developer please have my blessing to stop reading now :)
Still here? Cool, more geeky details:
Regarding Apollo 3, which should be released any day now, I was able to easily upgrade all my Apollo usage (Hooks time!), except for this link. I learned it wasn’t backwards compatible with 2. So I decided to fix that, take this library from Apollo 2 ->3, and while I was in there improve the test coverage. Gotta make the most of the Corona downtime right?
So this is a custom Apollo Link, written in TypeScript+ Jest. The Apollo Link API, if you haven’t already seen, is how you compose modular pieces to create the overall GraphQL client you want. For example if your needs grow beyond vanilla queries/mutations into subscriptions/’server push’ you’ll probably want the WebSocket Link. You also might use a custom link as your API usage gets more sophisticated e.g. if you’re interested in batching or retrying queries.
For me the best thing about this project is that from a user perspective, it’s effectively transparent – yet from a security perspective it does the token/auth dance in the proper way. Nice to see convenience and security go hand in hand for a change.
Here’s a quick refresher on the difference between vanilla sessions and JWTs. Session tokens tend to be returned in a web server response immediately after you POST a username & password. The session token is commonly stored in the browser as a cookie via the Set-Cookie HTTP header. Meanwhile with JWTs we typically deal with two tokens instead: access tokens, which are similar to session tokens in that they’re how you authenticate against an API, and tend to be short lived, e.g. 15 minutes. Refresh tokens on the other hand, live for longer, e.g. a week, and only let you get one thing: a new access token.
So when an access_token expires, the refresh_token, which might be stored as a cookie with appropriate path & security flags, is used to fetch a new access_token from the server.
In sum, what’s nice about this library is that when it detects an expired token, it intelligently queues incoming GraphQL operations and holds them until the token refresh dance is completed, at which point the queue is released and the operations can hit the server. All the while the user doesn’t have to do anything, they carry on as usual. Pretty decent balance of security and usability, at least for my needs!